Sunday, April 7, 2024
For DevOps Professionals: Analyzing and Eliminating Busy Work
Monday, December 26, 2022
Improve New Feature Delivery Rate with Value Stream Mapping
I constantly see a desire to deliver enhancements and additional business capabilities to end users at a faster rate. What I don't see is a methodical and data-driven approach to achieving a faster delivery rate. I typically use a tactic called value stream mapping to improve clients' speed to market. That tactic seems obvious to me but isn't used as widely as I think it should be.
I'm going to define and illustrate value stream mapping for you in hopes that you see the value and understand the tactic well enough to apply it to your existing production processes and procedures. The concept applies to application features, infrastructure features, DevOps automation capabilities, and just about any type of information technology process I can think of. In fact, it applies to any business process I can think of, including those that aren't IT-related.
Example Application Delivery Value Stream
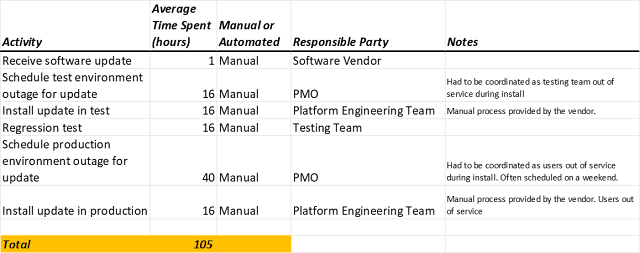
This is an example of the delivery process of a highly customized purchased application (COTS). As customizations were delivered by the vendor quite frequently, updates needed to be tested and deployed quite frequently. On average, the vendor supplied one to two updates per week. Each update required significant manual labor to test and deploy. The time and effort involved were costly and required tuning. We elected to do a value stream analysis.
Below are components of the value stream, along with how long manual time was spent testing and deploying them. Note that given the length of outage required for deployments, significant coordination with the testing team and business users was necessary and often extended the lag between updates received from the vendor and getting those updates into the hands of end-users.
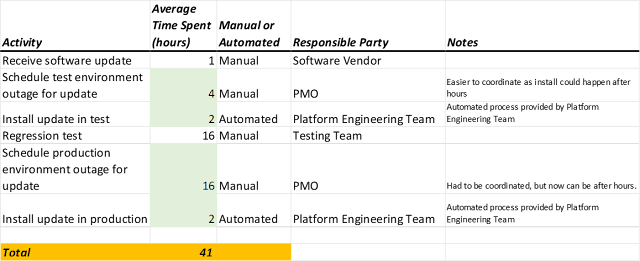
We decided to automate the deployment process. The procedure given to us by the vendor was entirely manual. While the deployment process was only 32 clock-time hours of the total, decreasing that time to 4 hours allowed much greater flexibility in scheduling updates in the test environment as well as production. Now, updating installations for the test environment could be done off-hours without putting the testing team out of service. Additionally, production updates could be deployed off-hours and no longer require the weekend.
Lessons Learned
Automating testing would be the logical next tuning step. That said, automating tests for a COTS application is easier said than done. This particular application did not lend itself to easy UI testing in an automated fashion. As we didn't have access to product source code, testing service APIs wasn't an option either.
The value stream tuning effort illustrated here works for custom applications just as well as it did for this COTS example. The value stream tactic applies the tuning principle of optimizing the largest targets (those that take the most time) first. This principle is used when we tune CPU or memory consumption in applications. In fact, the principal can be used for non-IT processes as well, like budgets.
Value stream analysis should be an ongoing effort repeated periodically. Over time, your deployment process changes. When that happens, the value stream will also change.
As with other types of tuning efforts, it's important to identify a specific target. Like other tuning efforts, it's always possible to keep improving. Having a target allows you to know when the tuning effort is "done" and effort can be directed elsewhere.
Value stream analysis often reveals business procedures and processes that are not optimal. In another example from the field, I've seen DNS entries and firewall rule entries that are forced by organizational procedures to be manual and take significant amounts of lead time. It's important to track these activities in the value stream process as well. You need accurate information to make effective tuning decisions.
Thanks for taking the time to read my article. I'm always interested in comments and suggestions.
Sunday, December 18, 2022
The Journey toward Continuous Delivery and Deployment: How to Start
Wednesday, September 14, 2022
Appropriate workloads for Kubernetes
I've been asked about hosting cloud applications in Kubernetes. People seem to assume that Kubernetes is the best practice for hosting containerized workloads in all cases. While I love Kubernetes and have used it successfully in numerous applications, It shouldn't be the default, out-of-hand, hosting solution for containerized workloads.
Kubernetes is far from the simplest solution for hosting containerized workloads. Even with cloud vendors making Kubernetes clusters more integrated and easier to manage, they are still very complex and take highly specialized administration skillsets. If you're using Azure, Containerized Instances is a comparatively more straightforward method than AKS for deploying containerized workloads. In fact, Azure has several different ways to deploy containerized workloads. Most are easier than AKS/Kubernetes.
If you're using AWS, ECS or Lambda is comparatively easier than Kubernetes. In fact, AWS has at least 17 ways to deploy containerized workloads. Incidentally, with any cloud, it's possible to create a virtual machine and run a containerized workload on it: I don't recommend this. Bottom line: Kubernetes AWS ECS, and Azure Containerized Instances are application runners.
If you adopt Kubernetes as a hosting mechanism, the benefits should pay for the additional complexity. Otherwise, the additional maintenance headaches and costs of Kubernetes are not a wise investment. That begs the question, what types of applications are most appropriate for Kubernetes? Which application types should adopt a more straightforward hosting mechanism?
As an aside, containerizing your applications is the mechanism that separates the concern of hosting from the functionality of your application. Cloud vendors have numerous ways to deploy and run containerized applications. Vendor lock-in usually isn't an issue with containerization.
Workloads Well-Suited for Kubernetes
Applications with dozens or hundreds of cloud-native services often benefit from Kubernetes. Kubernetes can handle autoscaling and availability concerns among the different services with less set-up per service. Additionally, cloud vendors have integrated their security and monitoring frameworks in a way that generally makes management of Kubernetes-hosted services homogenous with the rest of your cloud footprint.
Applications servicing multiple customers that require single-tenant deployments often benefit from Kubernetes. For these applications, there is one deployment of a set of services per "customer". For example, if there are 1000 customers, there will be 1000 deployments of the same set of services for each one. Given that the number of deployments grows and shrinks as customers come and go, Kubernetes streamlines the setup for each as well as provides constructs to keep each of the customer deployments separate.
Applications requiring custom Domain Name Services (DNS) resolution that can't be delegated to the enterprise custom DNS often benefit from Kubernetes. This is because Kubernetes has configurable internal networking capabilities. Often this happens more as a result of organizational structure than technical reasons. In many enterprises, DNS is managed by infrastructure teams and not application teams.
Applications in enterprises where IP address conservation is necessary can benefit from Kubernetes. For applications with internal services that only Kubernetes-hosted services needs access to, Kubernetes internal networking model called kubenet provides an internal network not visible outside the cluster. For example, an application with hundreds of microservices may only need to expose a small fraction of those services outside the cluster. The kubenet networking model conserves IP addresses as internal services don't need IP addressability outside the cluster.
In the cloud, we think of IP addresses as "free" and without charge. For firms with a large existing on premises network, IP address space is often not free. In most firms I've seen, on premises networks are tarballs without sensible IP address schemes. Often, nobody understands the entirety of what network CIDRs are in use and for what. Additionally, routing is often manually configured, making CIDR block additions labor-intensive.
Summary
Not every application should be hosted in Kubernetes. Simple applications with small transaction volume often don't require the additional complexity Kubernetes brings.
Thanks for taking the time to read this post. I hope this helps.
Sunday, September 4, 2022
Policy-based Management Challenges and Solutions
One of the most common best practices for managing security in the cloud is policy-based management. Policy-based management optimally prevents security breaches or at least alerts you to their presence. Additionally, it alieviates the need for as many manual reviews and approvals, which slow down development of new business capabilities. That said, policy-based management presents many challenges. This post details common challenges and tactics to overcome them.
Challenge #1: Introducing New or Changed Policies
Challenge #2: Policies with Automatic Remediation
Challenge #3: Adapting Policies to Advances in Technology
- Assuming that cloud vendor capabilities for securing network access remains the same. Often, these capabilities advance.
- Assuming VM IP addresses are static can safely be used in firewall rules. In the cloud, IP addresses can change quite frequently.
- Assuming that VM images are changeable (vended provided images might not be)
- Assuming that there will be no needed exceptions to security policies
Tactics to Mitigate Challenges
Summary
Monday, August 8, 2022
Move your Network to the Cloud Too!
- Complexity
- Performance
- Financial
- Speed to Market